Daily Edition · Page 1

THE DAILY INDEX

Technology, AI, software, security, crypto and business

Across today’s newsletters

Today’s Index
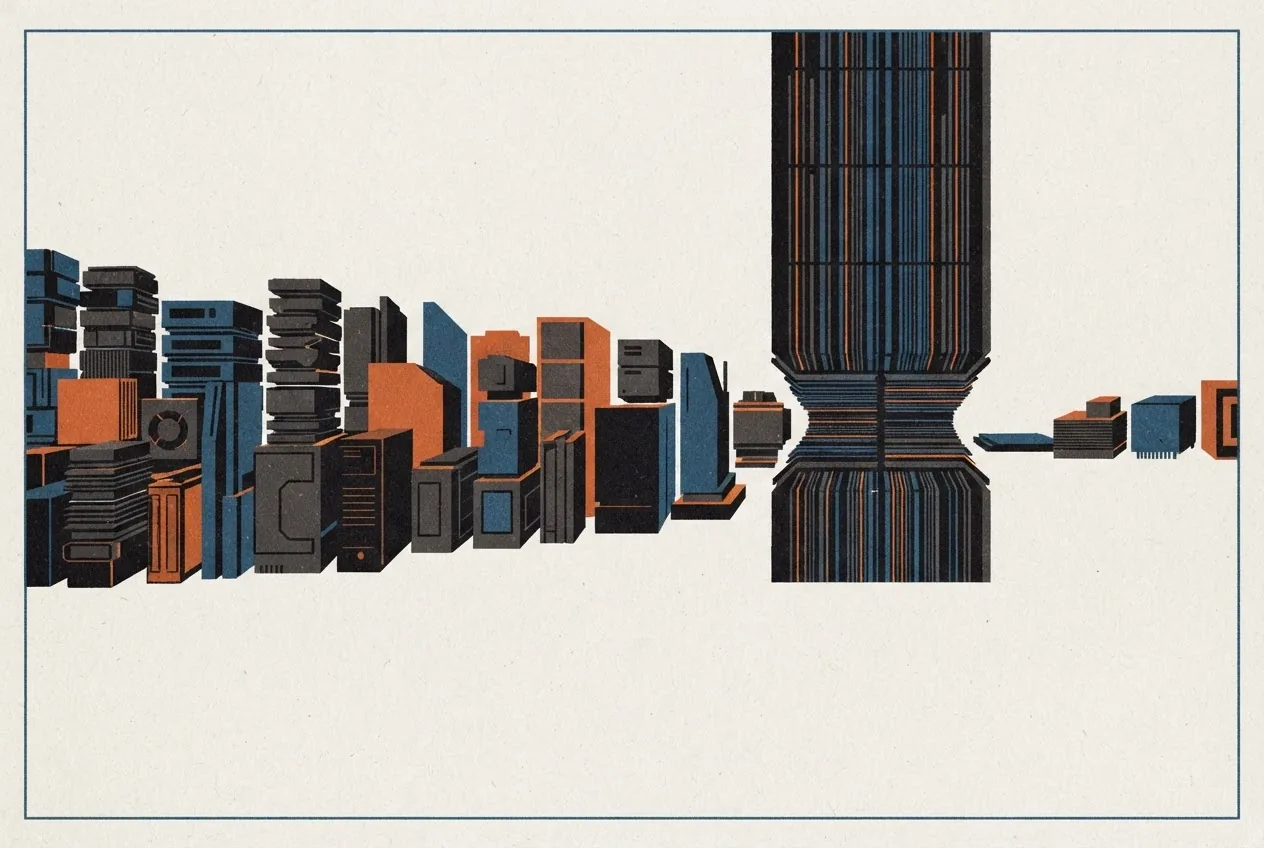
A queue of computing demands approaches a narrow passage made of layered material, illustrating how limited high-bandwidth memory and advanced packaging constrain AI compute growth.
AI-generated editorial illustration

COMPUTE SCARCITY IS PERMANENT. BUILD A LADDER

Processors are currently scarce because of the same bottleneck: the high-bandwidth memory and the advanced packaging that binds it to the die are capacity-limited across the entire industry. This can't be fixed with a bigger cloud budget or a patient retry loop. This constraint isn't clearing anytime soon and is likely a permanent condition. Businesses need to build for this reality rather than waiting for the shortage to end.

SMART ROUTING IN UNITY AI GATEWAY: MATCH FRONTIER QUALITY WITH 30%+ LOWER COST PER TASK

Databricks has launched Smart Routing in Beta through its Unity AI Gateway, a system that automatically matches coding tasks to models based on complexity rather than defaulting to the most expensive option. On internal workloads, Smart Routing outperformed any single model at 65% of the cost per task compared to a leading model like Opus 5, and matched Opus 5 on public benchmarks at less than half the cost. The system works natively inside Claude Code and Codex, and also runs through Omnigent, Databricks' meta-harness that routes across both models and coding harnesses. A lightweight classifier reads each task and labels it across several fields before the router decides whether to escalate to a frontier model or delegate to a cheaper one.

X OPEN SOURCES ITS RANKING ALGORITHM, LETTING USERS SEE IF THEY'VE BEEN ‘SHADOWBANNED'

X has open-sourced its 'For You' algorithm and its core ranking engine under the Apache v2 license. The company has also expanded its previous efforts to open source parts of its codebase to add more detail, making it roughly 10 to 15 times larger than it was before. X is providing tools that will let users see for themselves if and how its ranking systems have impacted their account or posts. The tool will be available to a test group of accounts for at least a year as a pilot before rolling out more broadly.

ANNOUNCING: DOCKER VMM PUBLIC BETA

Docker has released a public beta of Docker VMM, a new first-party virtualization layer built in-house, available in Docker Desktop v4.86 for Mac and Windows. The new engine replaces the third-party VMM Docker Desktop previously relied on, and promises faster container startup, better file I/O, and smarter memory management that returns RAM to the host when containers are idle. Windows users can opt in via Settings, General, and the Docker VMM option. General availability is targeted for the end of October, when Docker VMM becomes the default engine for new installs across Mac, Windows, and Linux.

CHOOSING AN AI MODEL: ONE PROMPT, 11 MODELS, VERY DIFFERENT RESULTS

A range of AI models, including DeepSeek, Qwen, and Kimi, were tested for generating web pages, showing large variations in performance and credit costs. The best-performing models for a static coffee shop website were DeepSeek V4 Flash, which consumed only 2.4 credits on average, and GPT 5.6 Sol in low effort mode, which averaged 141 credits. In contrast, higher-tier models like Claude Opus 5 showed a lot of credit usage with results that didn't necessarily justify their cost.

MEASURING TIME SAVINGS FROM FIGMA MAKE

Figma's Data Science team ran a randomized controlled trial with 100 participants to measure how much time Figma Make actually saves on design tasks. Design work was found to be 20% faster and 16% easier overall, with product managers seeing the largest gains—23% faster and 37% easier—though designers benefited most on complex tasks while PMs gained more on simpler ones. Figma plans further RCTs, including one testing its new design agent's parallel-agent capabilities.

COINBASE LAUNCHES NEW DERIBIT MATCHING ENGINE

Coinbase deployed a new matching engine on Deribit capable of processing over 100,000 orders per second with sub-millisecond latency, bringing the options exchange onto the same core execution infrastructure as Coinbase International Exchange. The engine introduces brief delays for aggressive orders on select instruments, giving liquidity providers additional time to reprice quotes during fast-moving markets. Coinbase plans to migrate all perpetual futures contracts to the engine before year-end, consolidating its derivatives stack across venues.

LOCKHEED'S X-62 VISTA FLIES 27 AI-CONTROLLED AIR INTERCEPTS USING LIVE SENSOR DATA

Lockheed Martin Skunk Works and the US Air Force Test Pilot School flew the X-62 VISTA, a variable-stability test aircraft, through eight flights in which an onboard AI agent completed 27 autonomous air intercepts against a live T-38 target. The aircraft carried Lockheed's Legion Pod, an infrared search and track sensor that fed live targeting data directly to the AI, which then independently worked out the target's position and flight path and maneuvered the aircraft into intercept position, closing the full sensor-to-action loop in real time rather than in simulation. It builds on Lockheed's Supermassive AI framework, developed and flight-validated in roughly three months, with the next phase integrating RTX's PhantomStrike radar and expanded sensor and compute capacity onto the X-62 for further mission-systems testing.

TLDR IndexPage 1